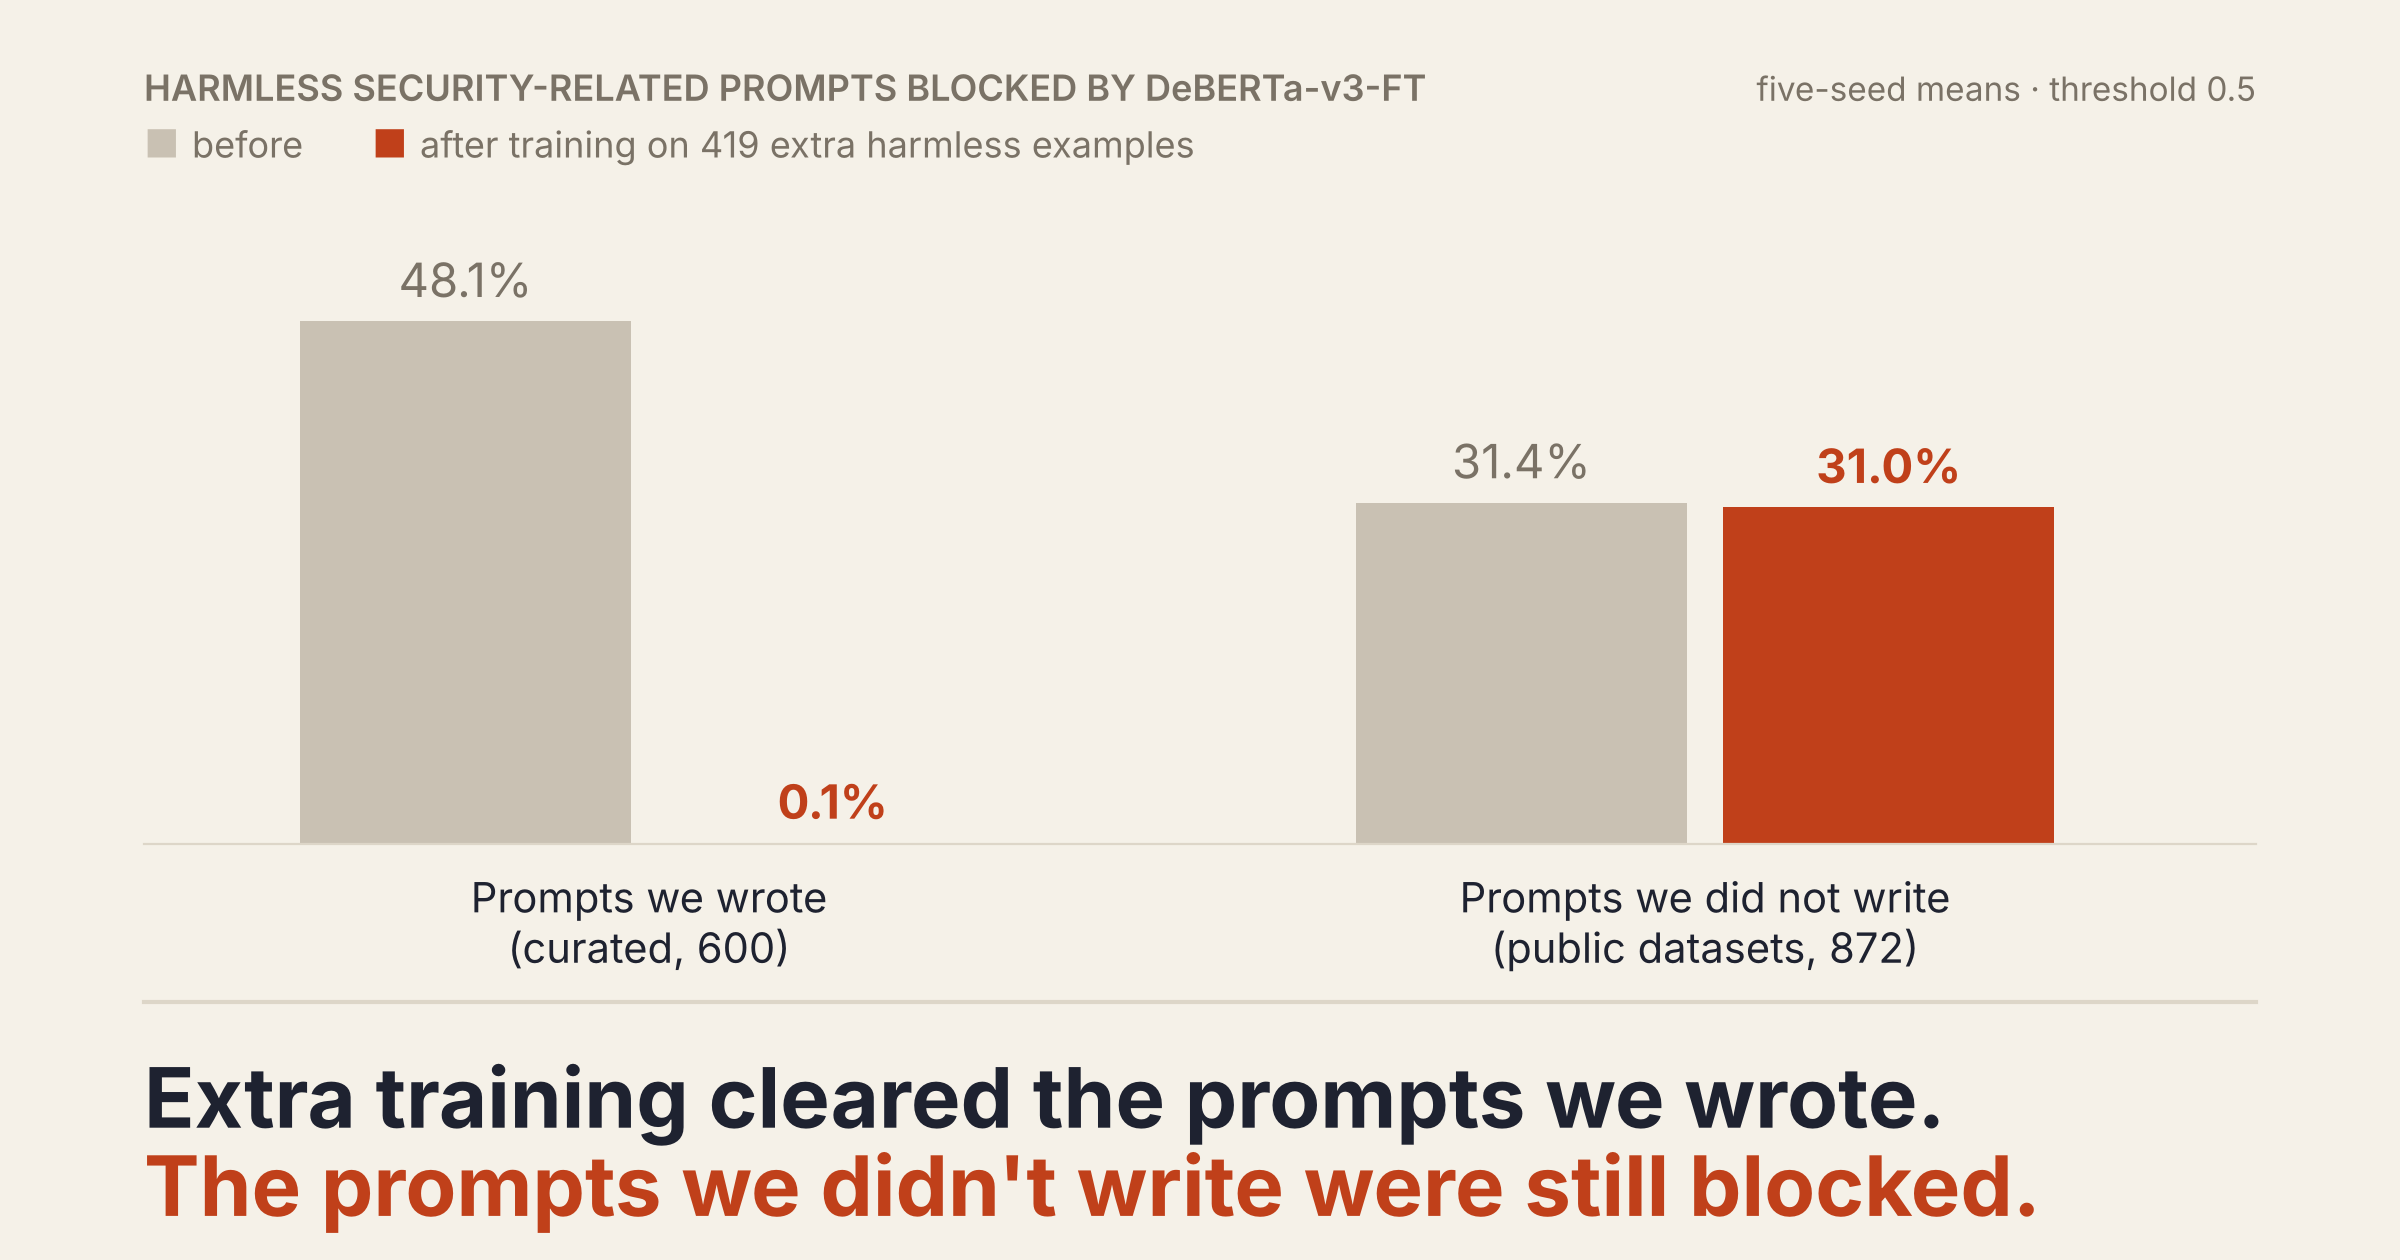
Bar chart of harmless security-related prompts blocked by DeBERTa-v3-FT, before and after training on 419 extra harmless examples. Prompts we wrote (600): 48.1% before, 0.1% after. Prompts we did not write, from public datasets (872): 31.4% before, 31.0% after. Headline: Extra training cleared the prompts we wrote. The prompts we didn't write were still blocked.

Prompt-injection detectors, tested on prompts they should let through

A detector with F1 0.988 still blocked about a third of harmless, security-related prompts from public datasets. No threshold fixed it, and extra training only fixed the prompts we had written ourselves.

October 11, 2026 · 19 min · Yusuf Khalid Shire